

Team
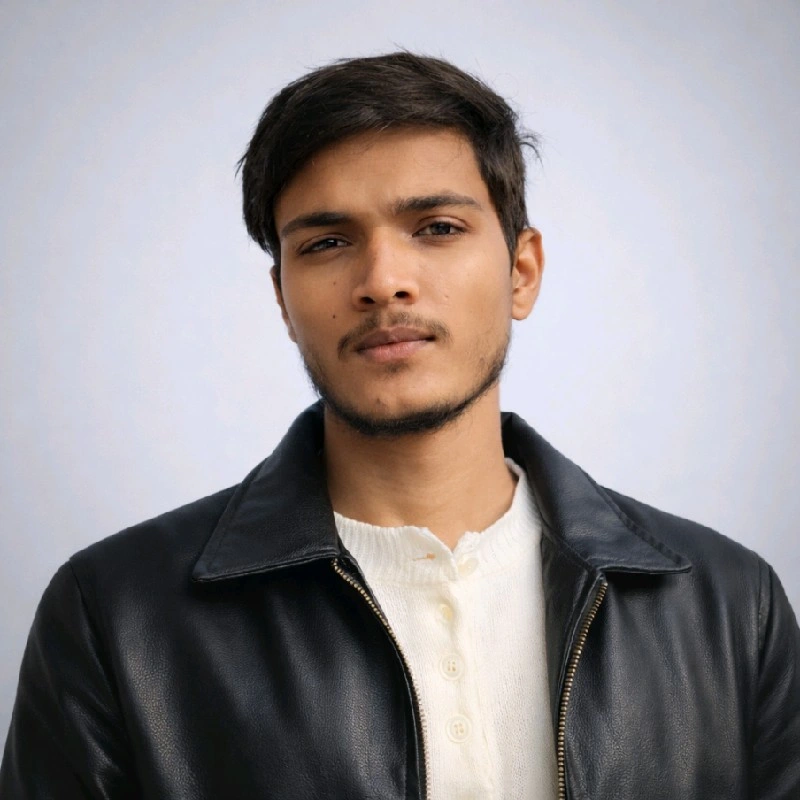
Co-founder & Research Lead
Rehan
Directing cognitive reverse proxy theory, real-time Shannon entropy classifiers, and uncertainty calibration at GlyIQ Infrastructure.
- 5
- Research works
- 99.4%
- Parity win-rate
- 1.8 ms
- P50 Latency
- 78%
- Cost savings
- October 2026
- Cohort
About
Directing cognitive reverse proxy theory, real-time Shannon entropy classifiers, and uncertainty calibration at GlyIQ Infrastructure.
Focused on mathematical bounds of multi-turn inference and deterministic routing parity.
Writes about
Research & Notes 5
- Controlling LLM API Cost: A Practical FinOps Guide A practical engineering guide for LLM API cost control, token accounting, model selection, prompt size, retries, caching, and bounded agent limits.
- Caching for LLM Applications: Response Reuse and Prompt Prefixes Three distinct caching mechanisms for LLMs: exact-response caches, semantic cache risks, provider prompt prefix reuse, and cost models.
- Retrieval-Augmented Generation and Long-Context Input A decision guide for choosing what evidence to send to a model: retrieval pipelines, context budgets, latency, and cost modeling.
- Multi-Agent Workflows: Coordination Cost and Control Explore multi-agent workflow failure modes, history-growth models, coordination token overhead, and bounded control architectures.
- Small Models, Fine-Tuning, and Serving Economics Evaluate smaller open-weight models, quantization, LoRA fine-tuning, knowledge distillation, and break-even self-hosting economics.
- Intelligence Is Getting Cheaper to Build. Why Is It Still So Expensive to Run? The cognitive execution layer: semantic vector RAM, adaptive routing, and zero-waste inference economics.